-
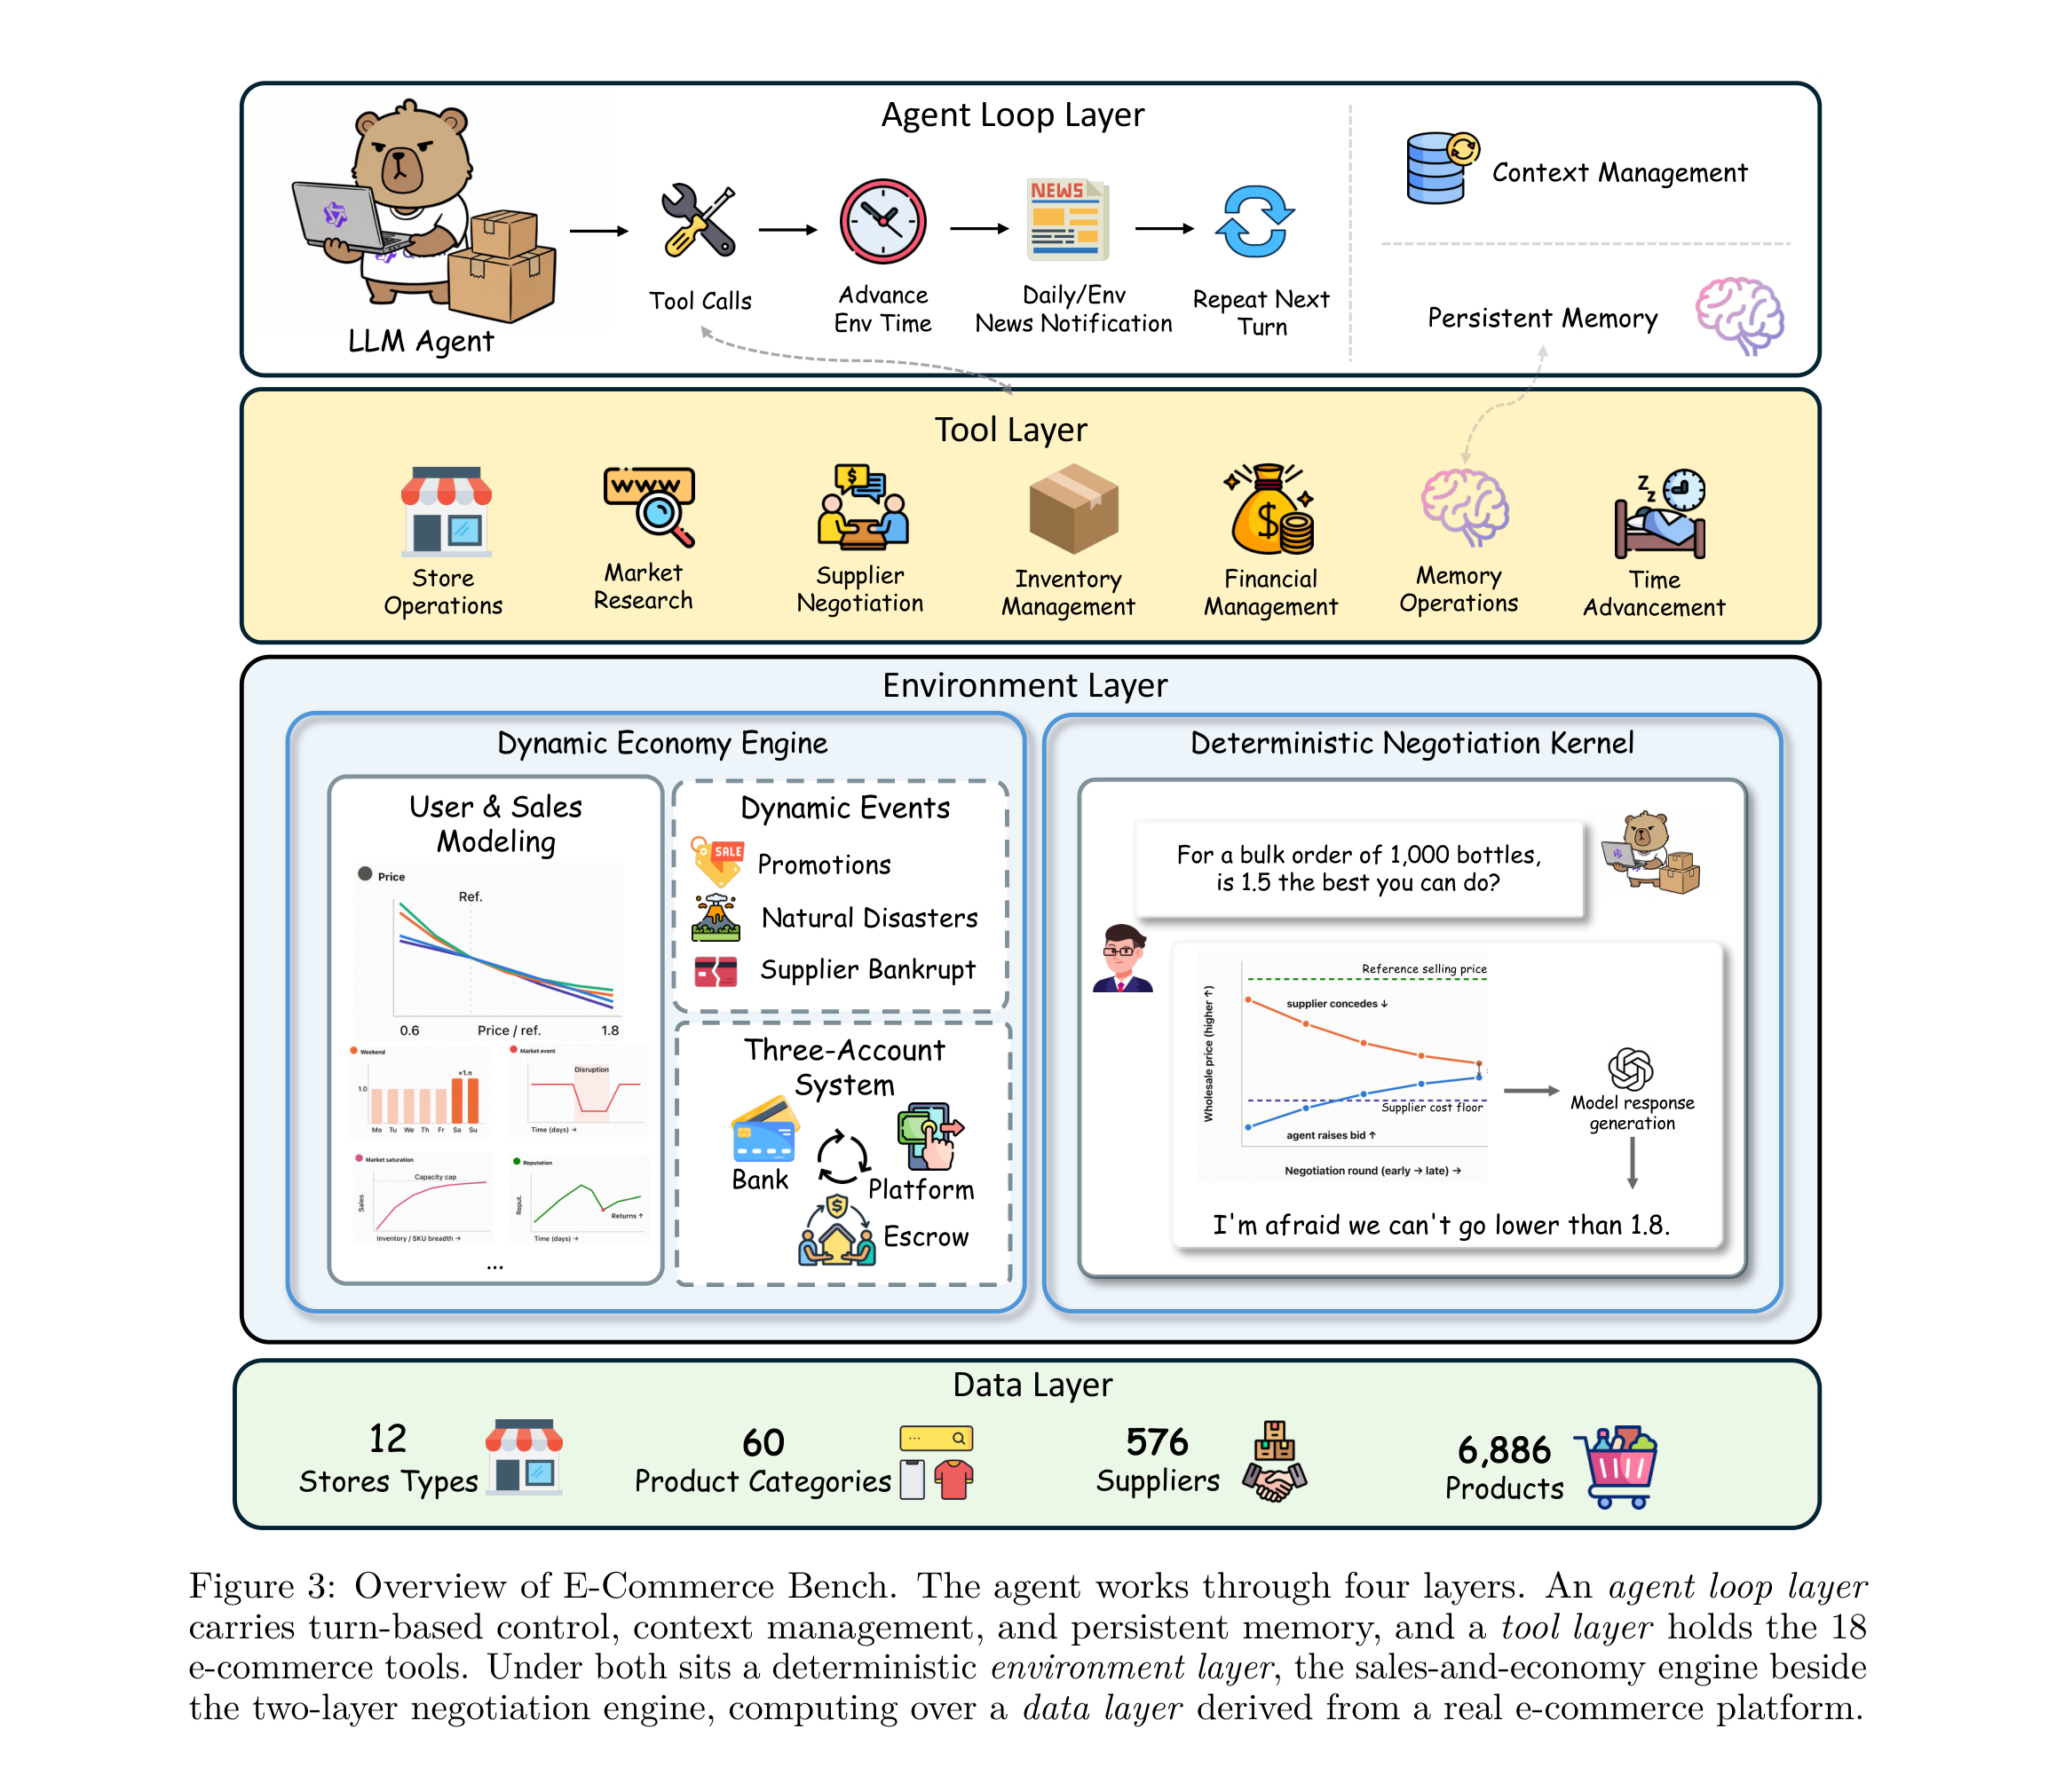
[Paper Review] E-Commerce Bench: Evaluating LLM Agents on Long-Horizon Autonomous Business Operation
A year of simulated commerce exposes distinct strengths in profit, liquidity, fraud avoidance, and experience reuse across 18 LLM agents.
-
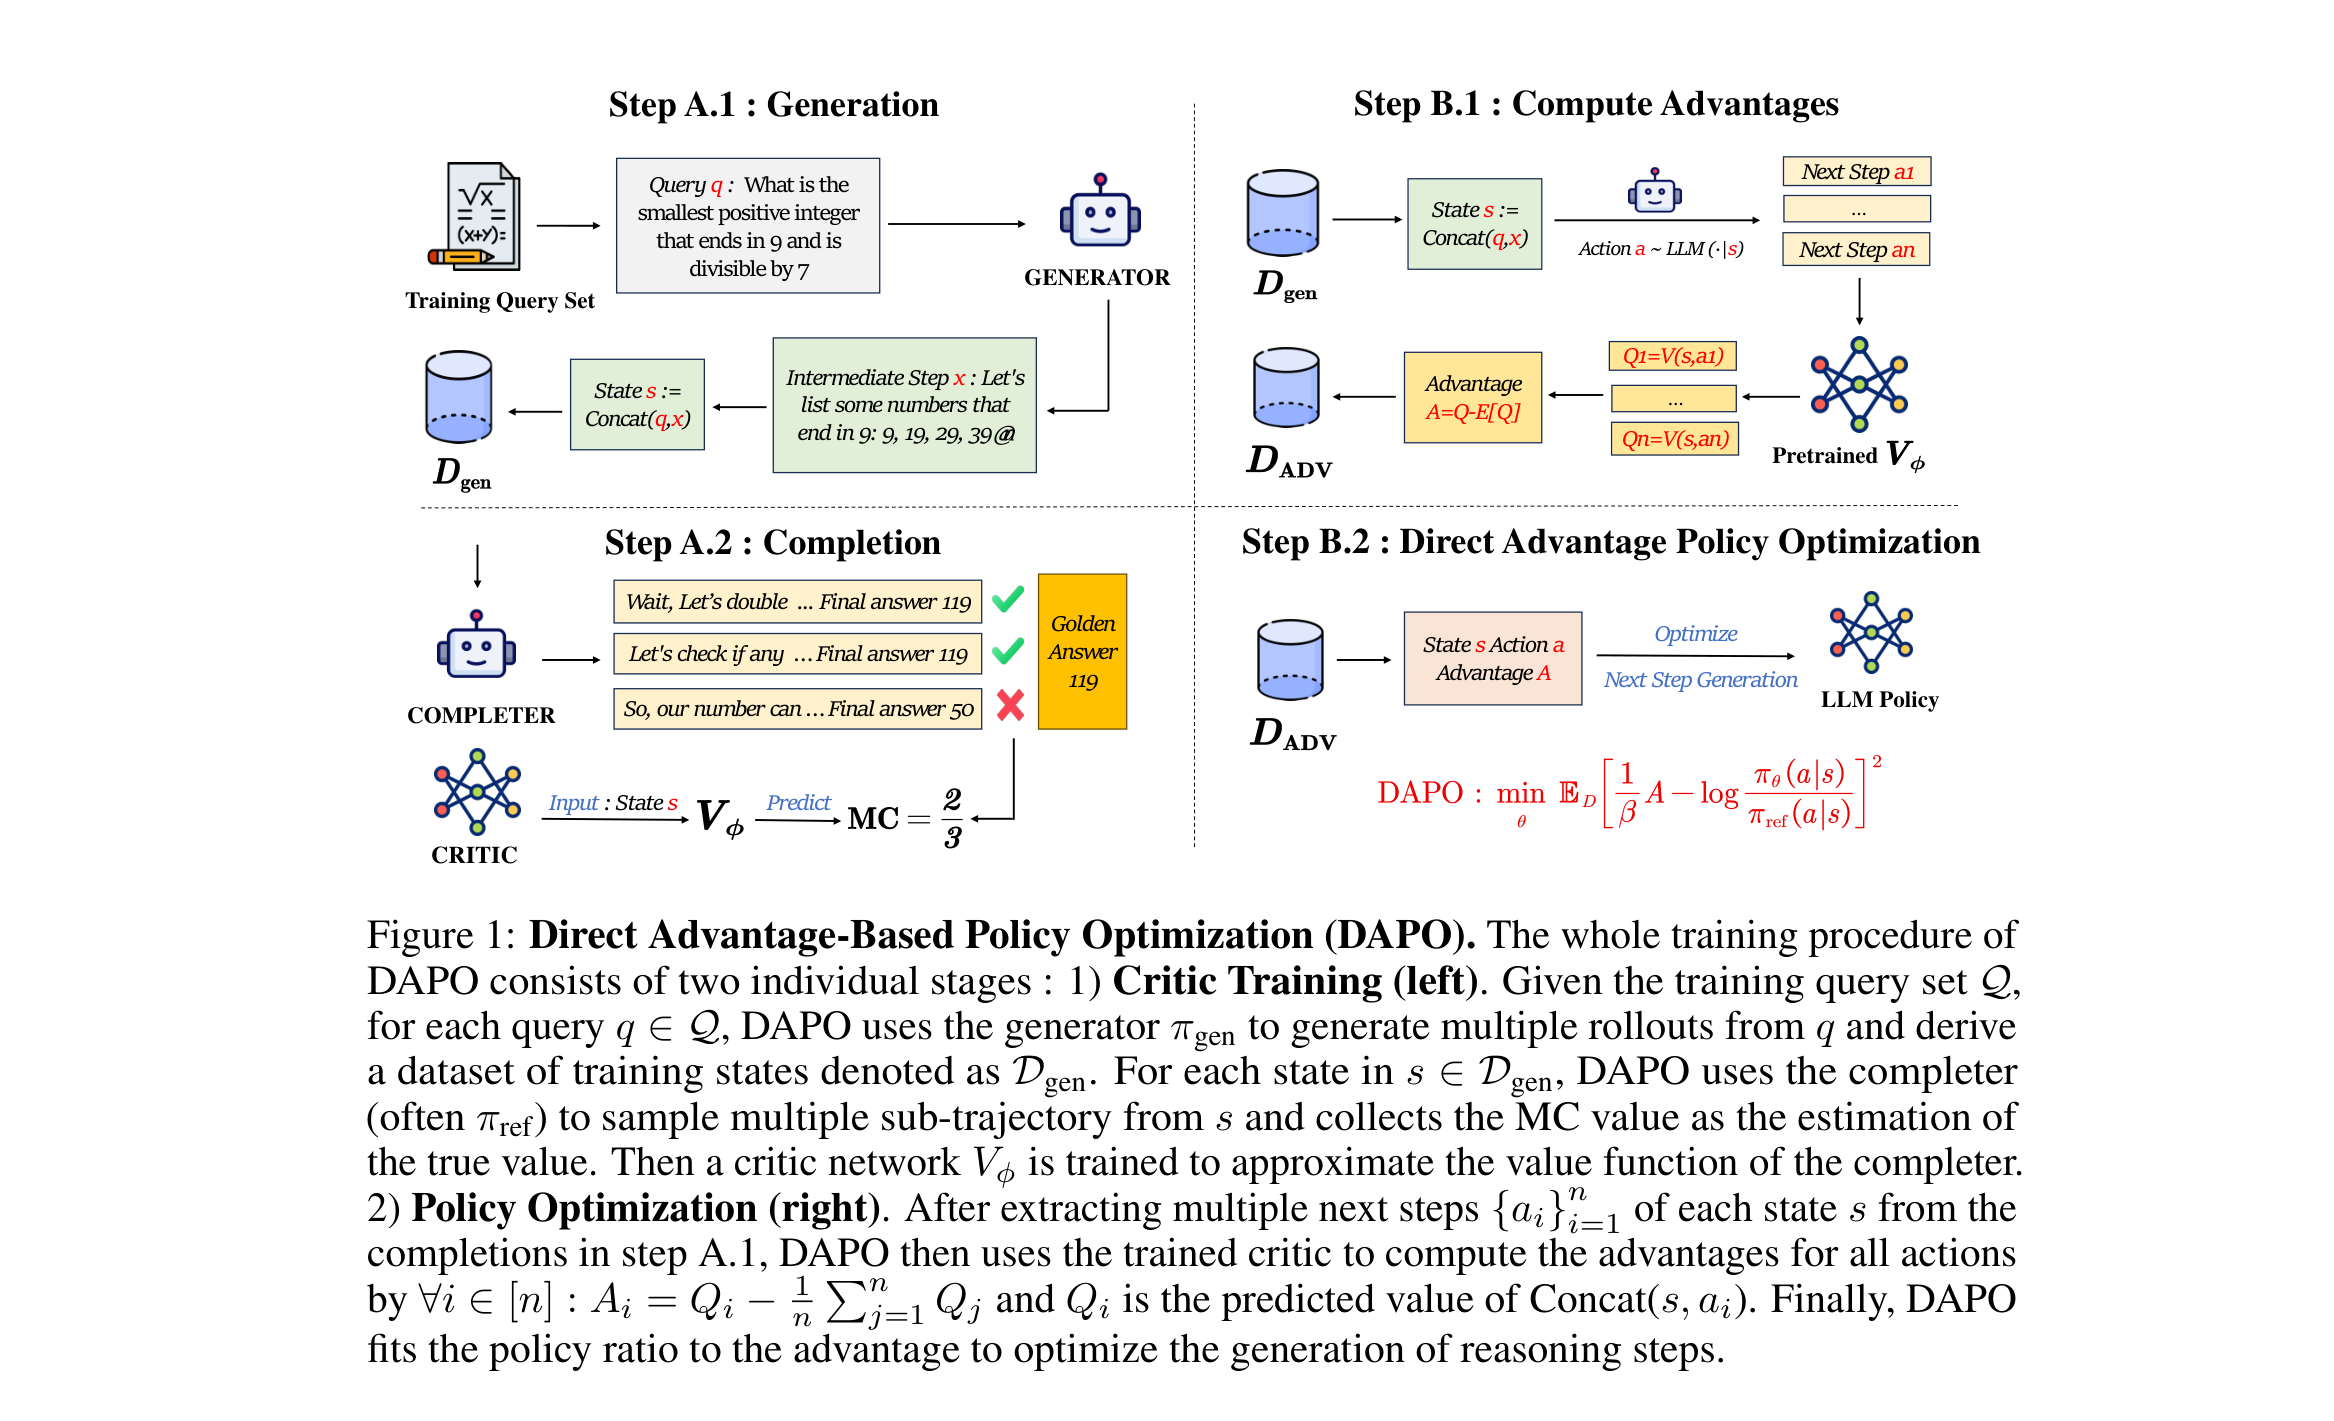
[Paper Review] DAPO: Improving Multi-Step Reasoning Abilities of Large Language Models with Direct Advantage-Based Policy Optimization
Offline step-level RL through advantage regression: DAPO's critic training, conditional improvement guarantee, math and code results, and computational costs.
-
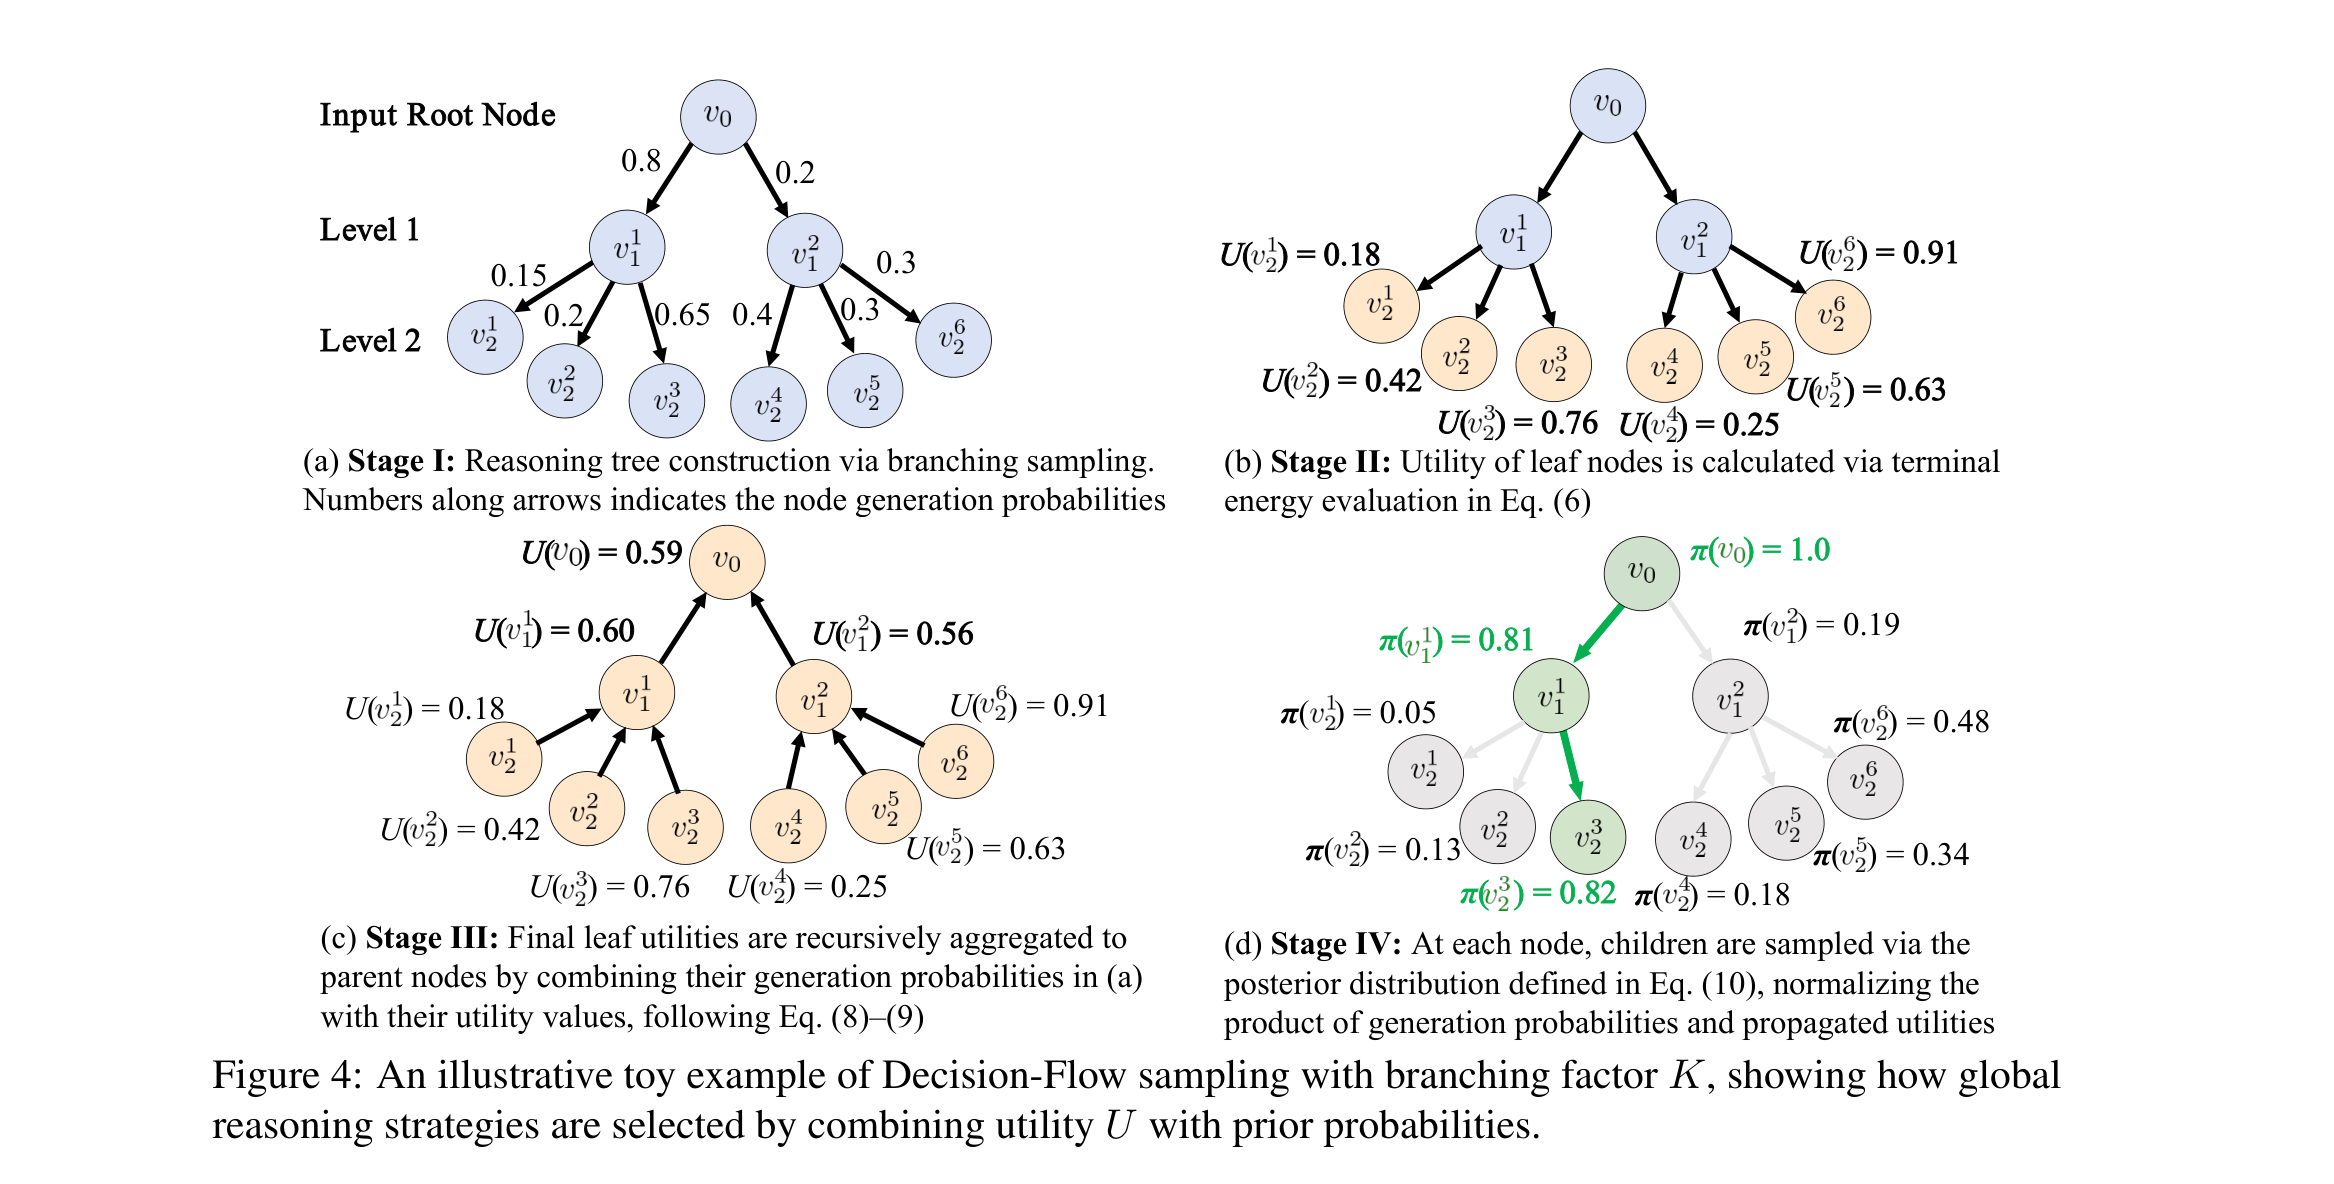
[Paper Review] Sampling via Decision-Flow: Training-Free Extraction of Improved Latent Reasoning Paths in Large Language Models
How DF-Sample combines reasoning trees, terminal energy, and backward utilities, and what its GPT-4o evaluator, benchmark exceptions, and search costs imply.
-
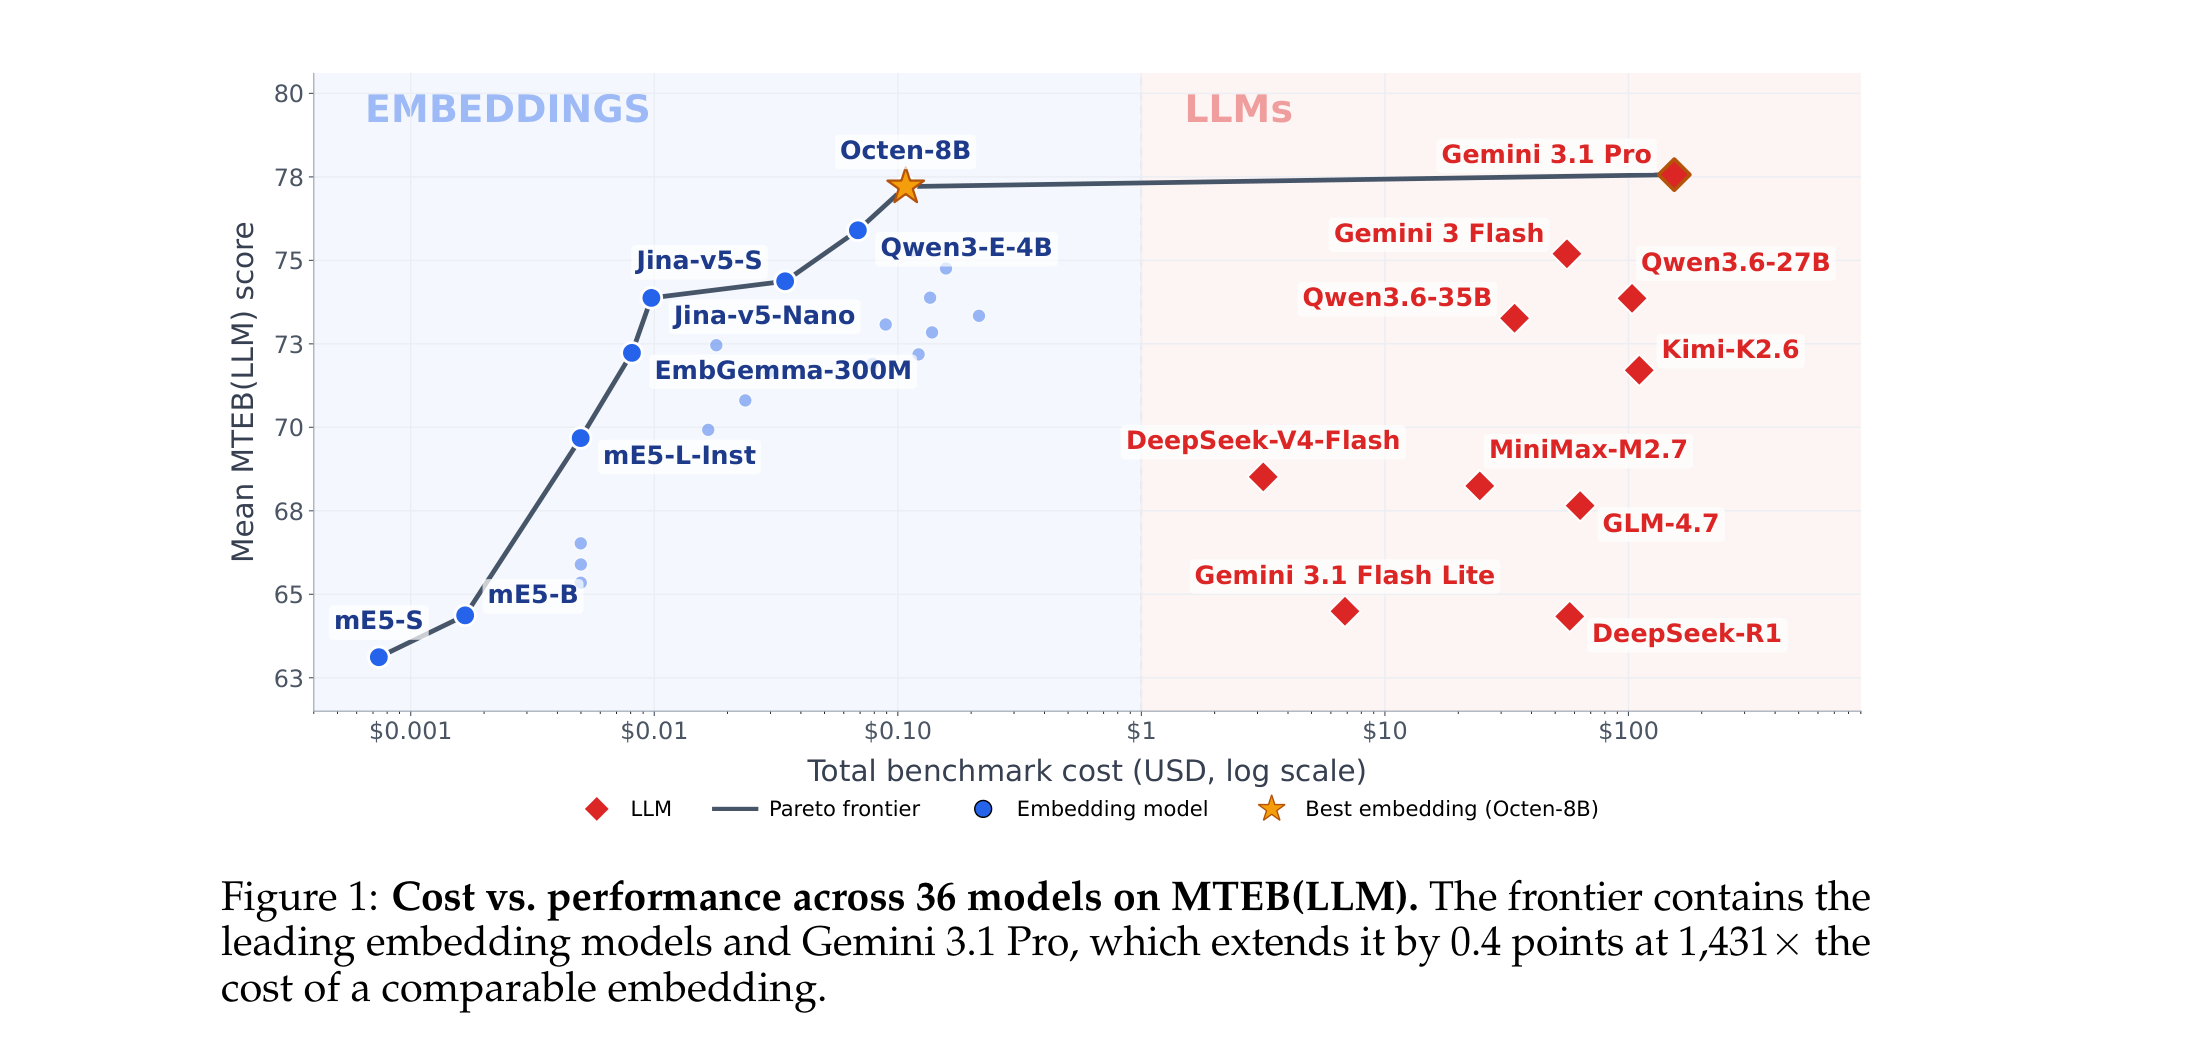
[Paper Review] The Embedder's Dilemma: LLMs Are Better, but at What Cost?
A close reading of MTEB(LLM): embedding versus generative pipelines, inference costs, reranking, and the limits of the comparison.
-
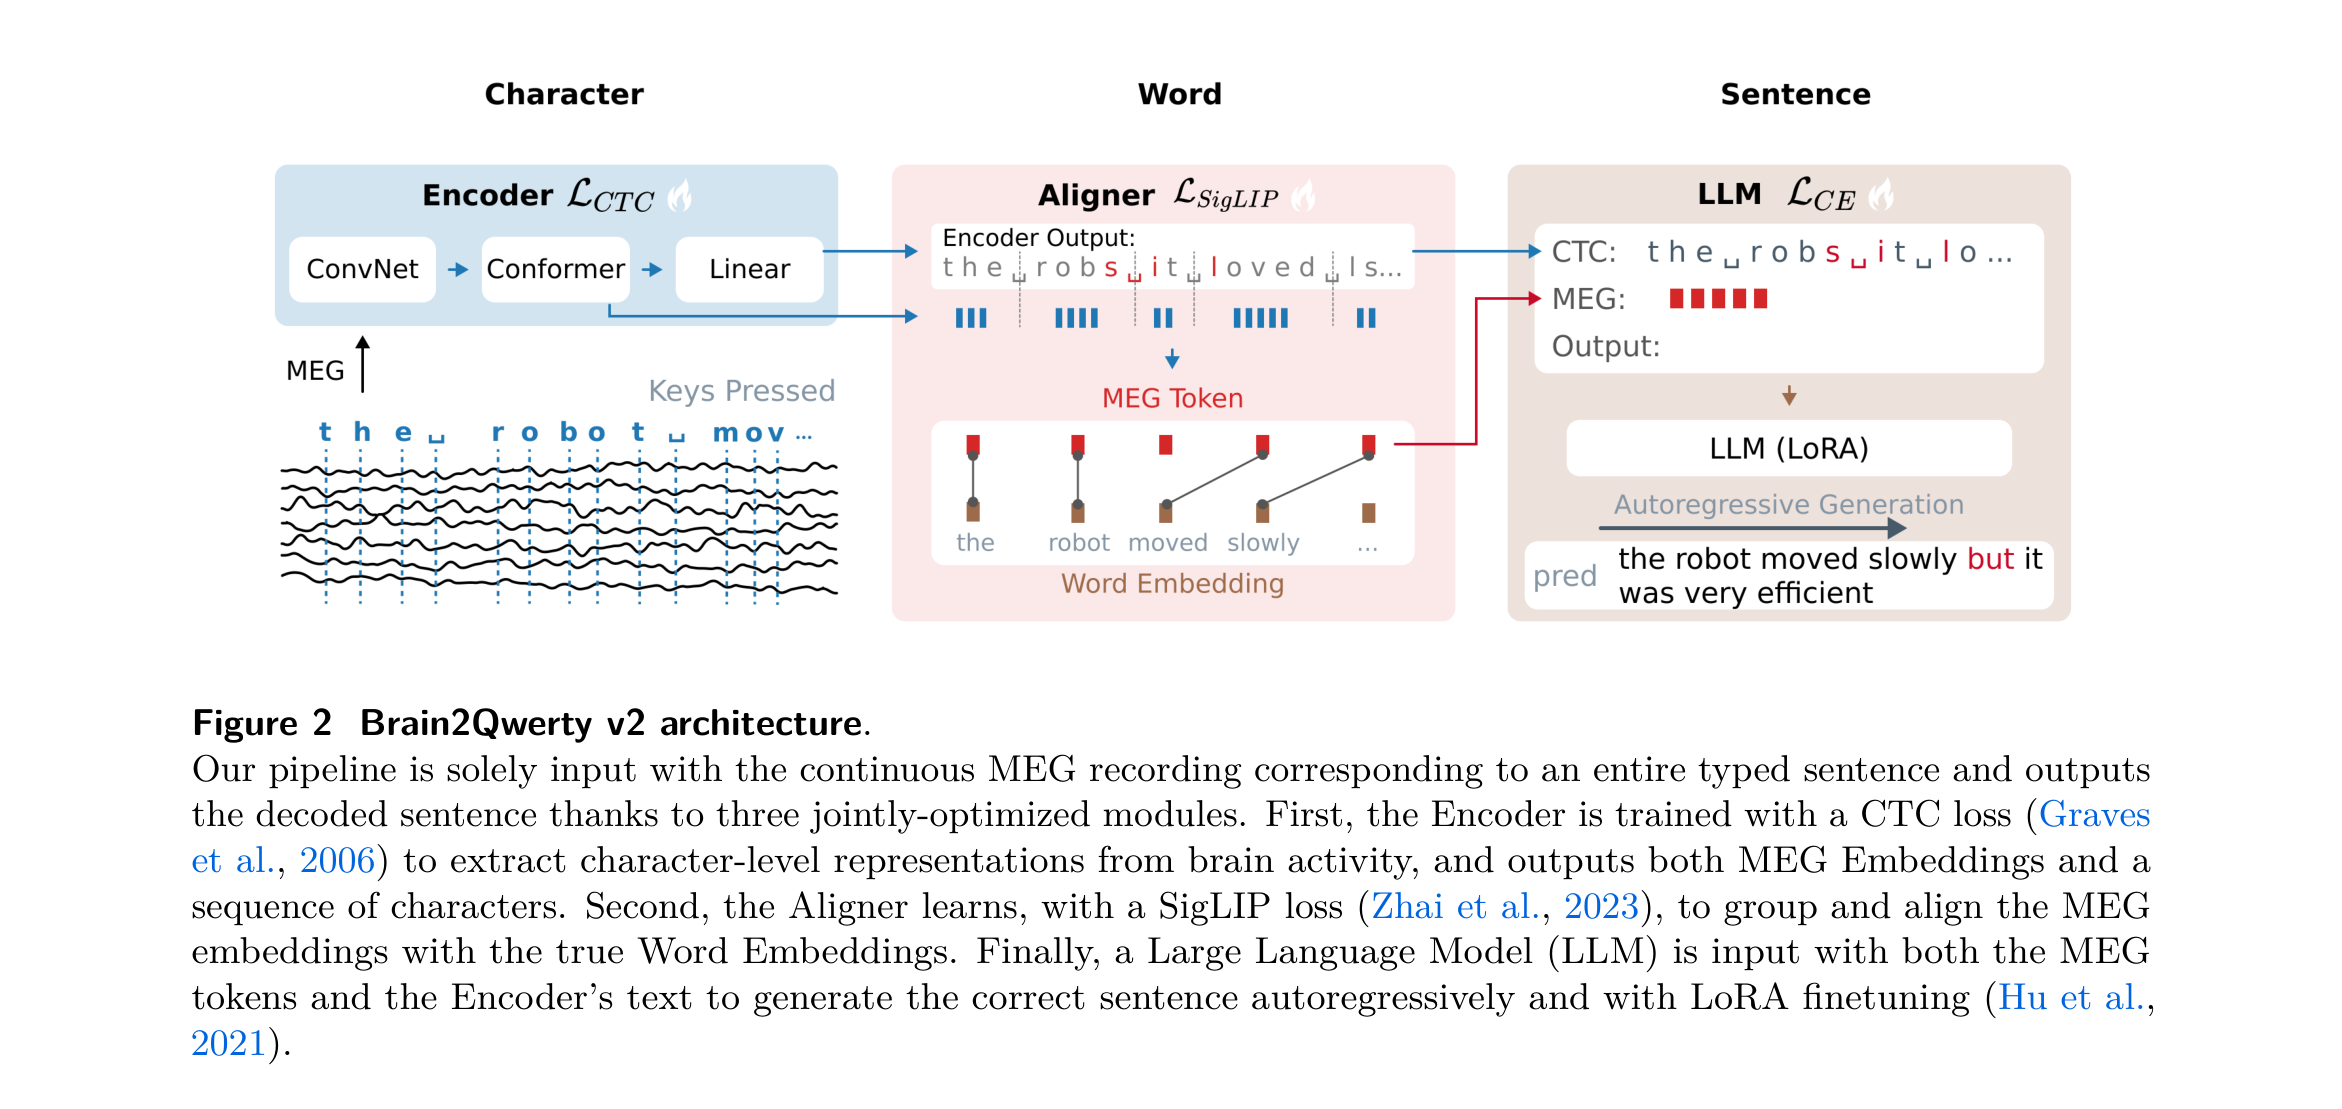
[Paper Review] Accurate Decoding of Natural Sentences from Non-Invasive Brain Recordings
Meta AI's Brain2Qwerty v2 collects 90 hours and 2,724 unique sentences of MEG from nine people, then chains a CTC encoder, a word aligner, and a LoRA-tuned LLM to decode natural sentences from non-invasive brain signals at 39% WER
-
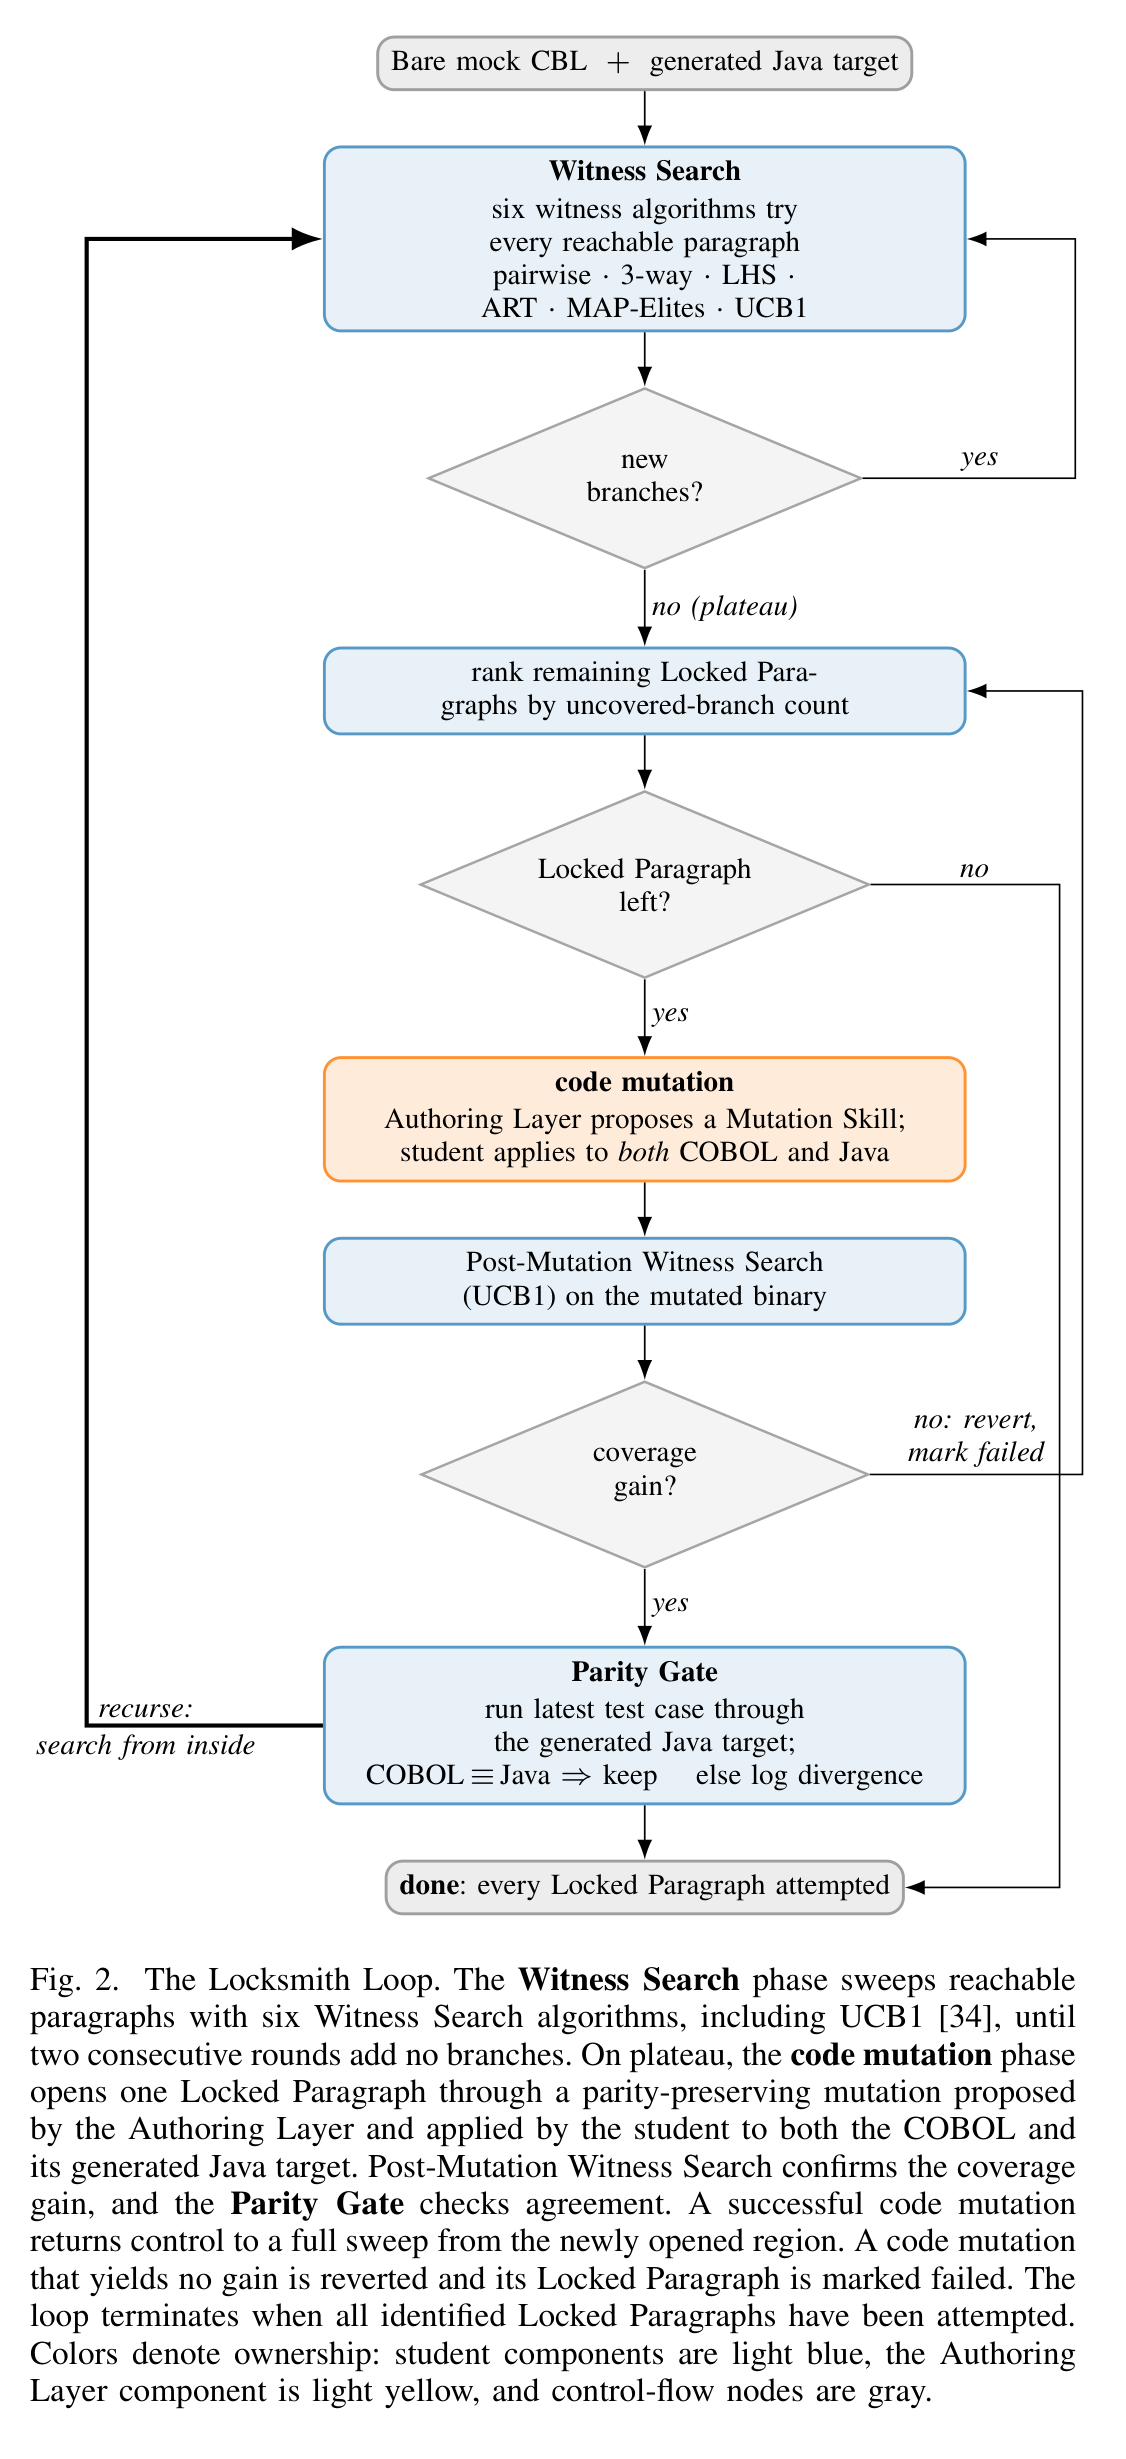
[Paper Review] Agentic Method for Deterministic Validation of Legacy Code Migration
American Express's Locksmith Loop: when input search stalls during COBOL-to-Java migration validation, mutate the harness itself to open new execution regions, apply the mutation symmetrically to both languages, and let a deterministic parity oracle decide what survives
-
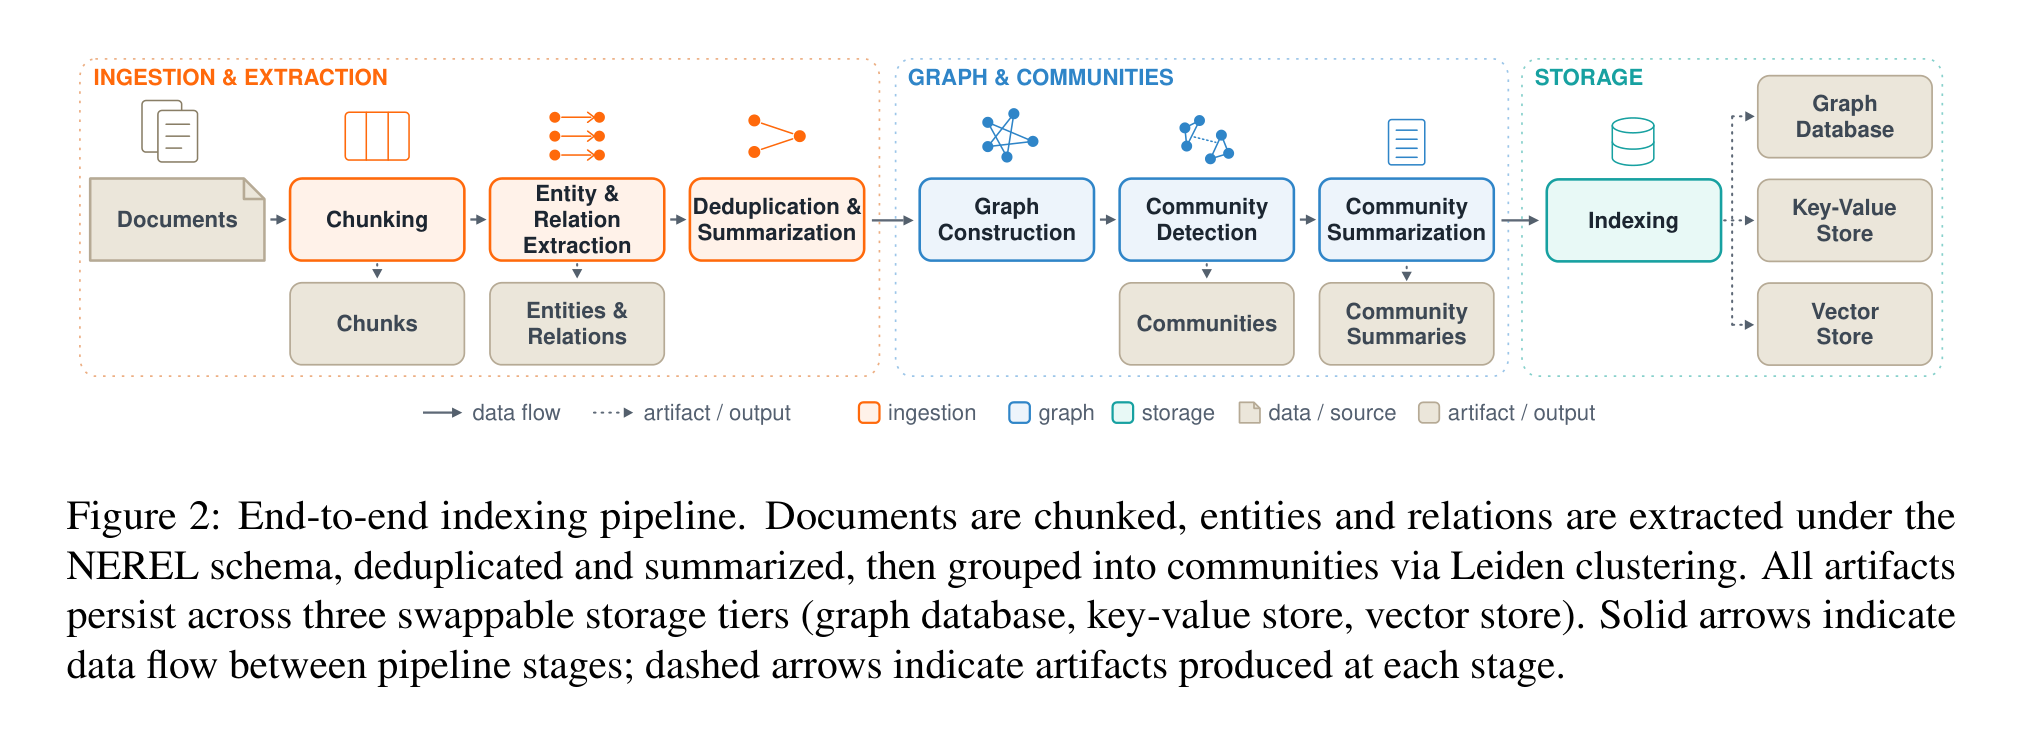
[Paper Review] RAGU: A Multi-Step GraphRAG Engine with a Compact Domain-Adapted LLM
A GraphRAG engine that separates extraction from consolidation, and a scaling hypothesis that justifies running the whole indexing pipeline on a 7B model
-
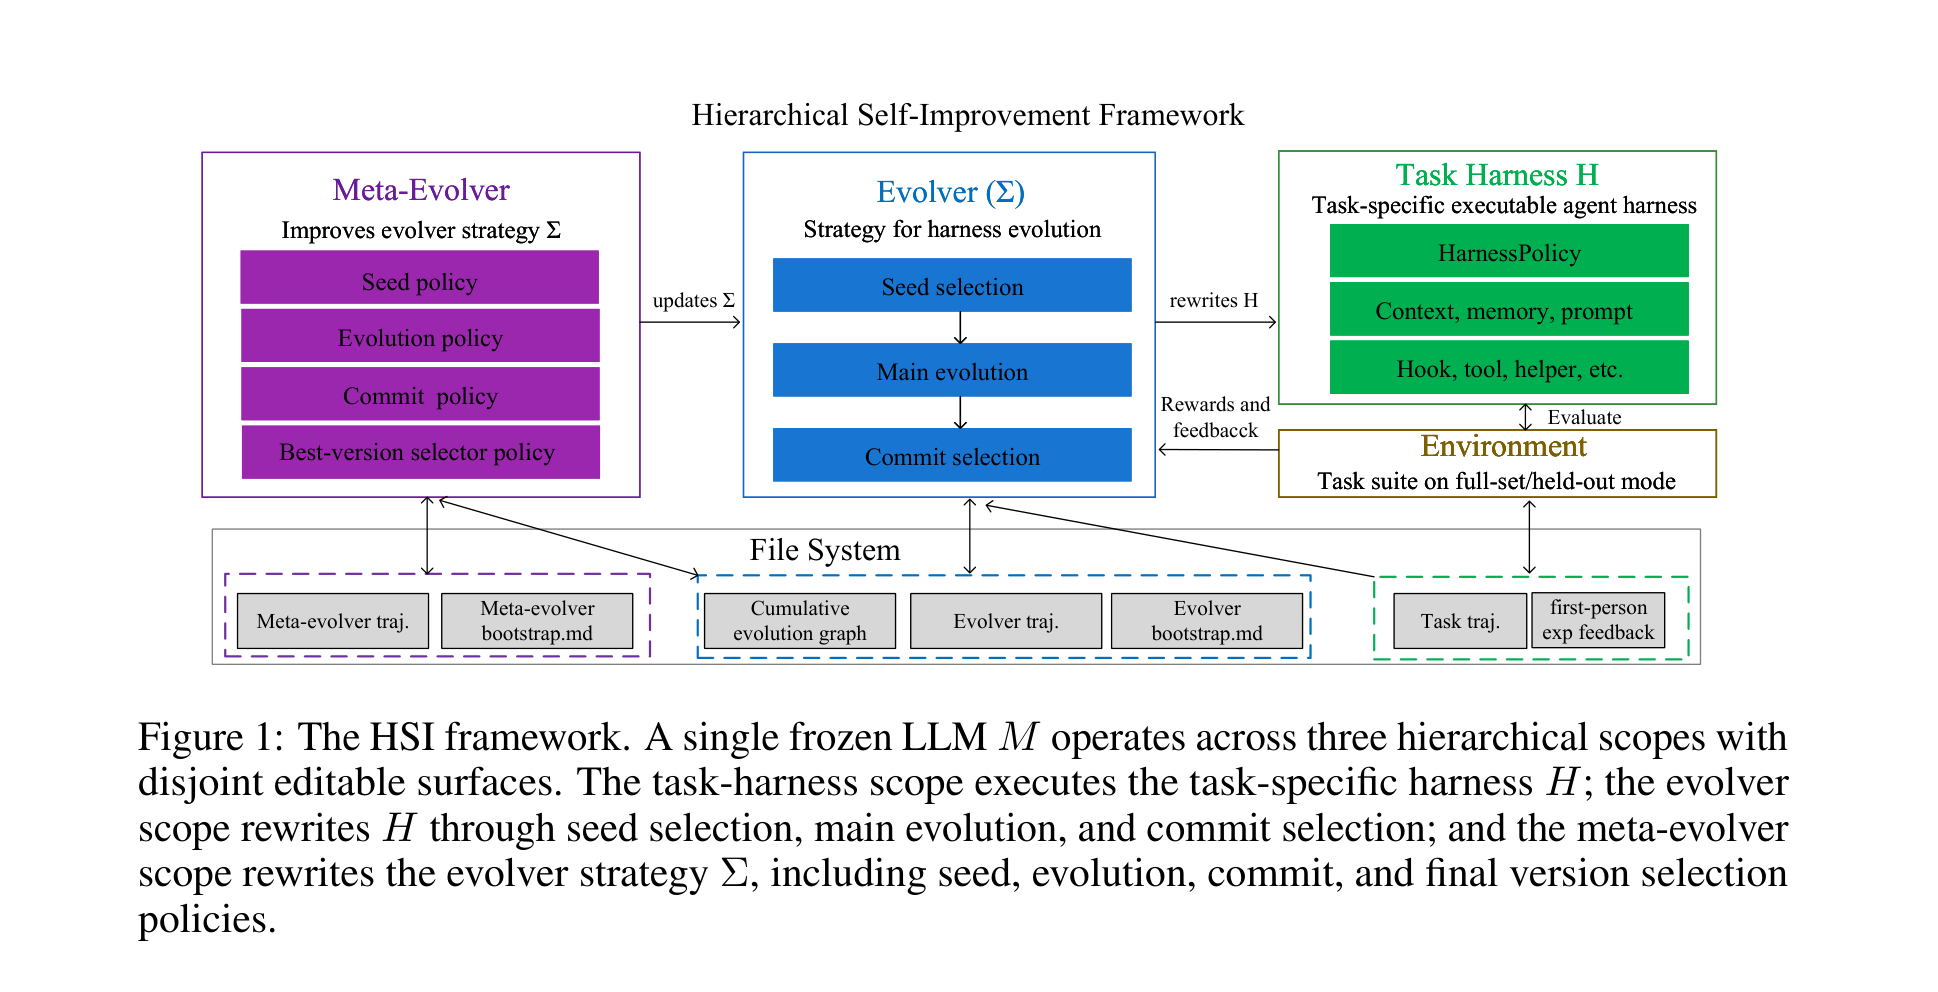
[Paper Review] Hierarchical Self-Improvement: A Framework for Task-Specific Evolvable Agent Harnesses
Freeze the model, evolve only the harness across three nested scopes — +39.3 on BabyAI and +33.0 on Crafter, plus an honest account of exactly where the gains stop
-
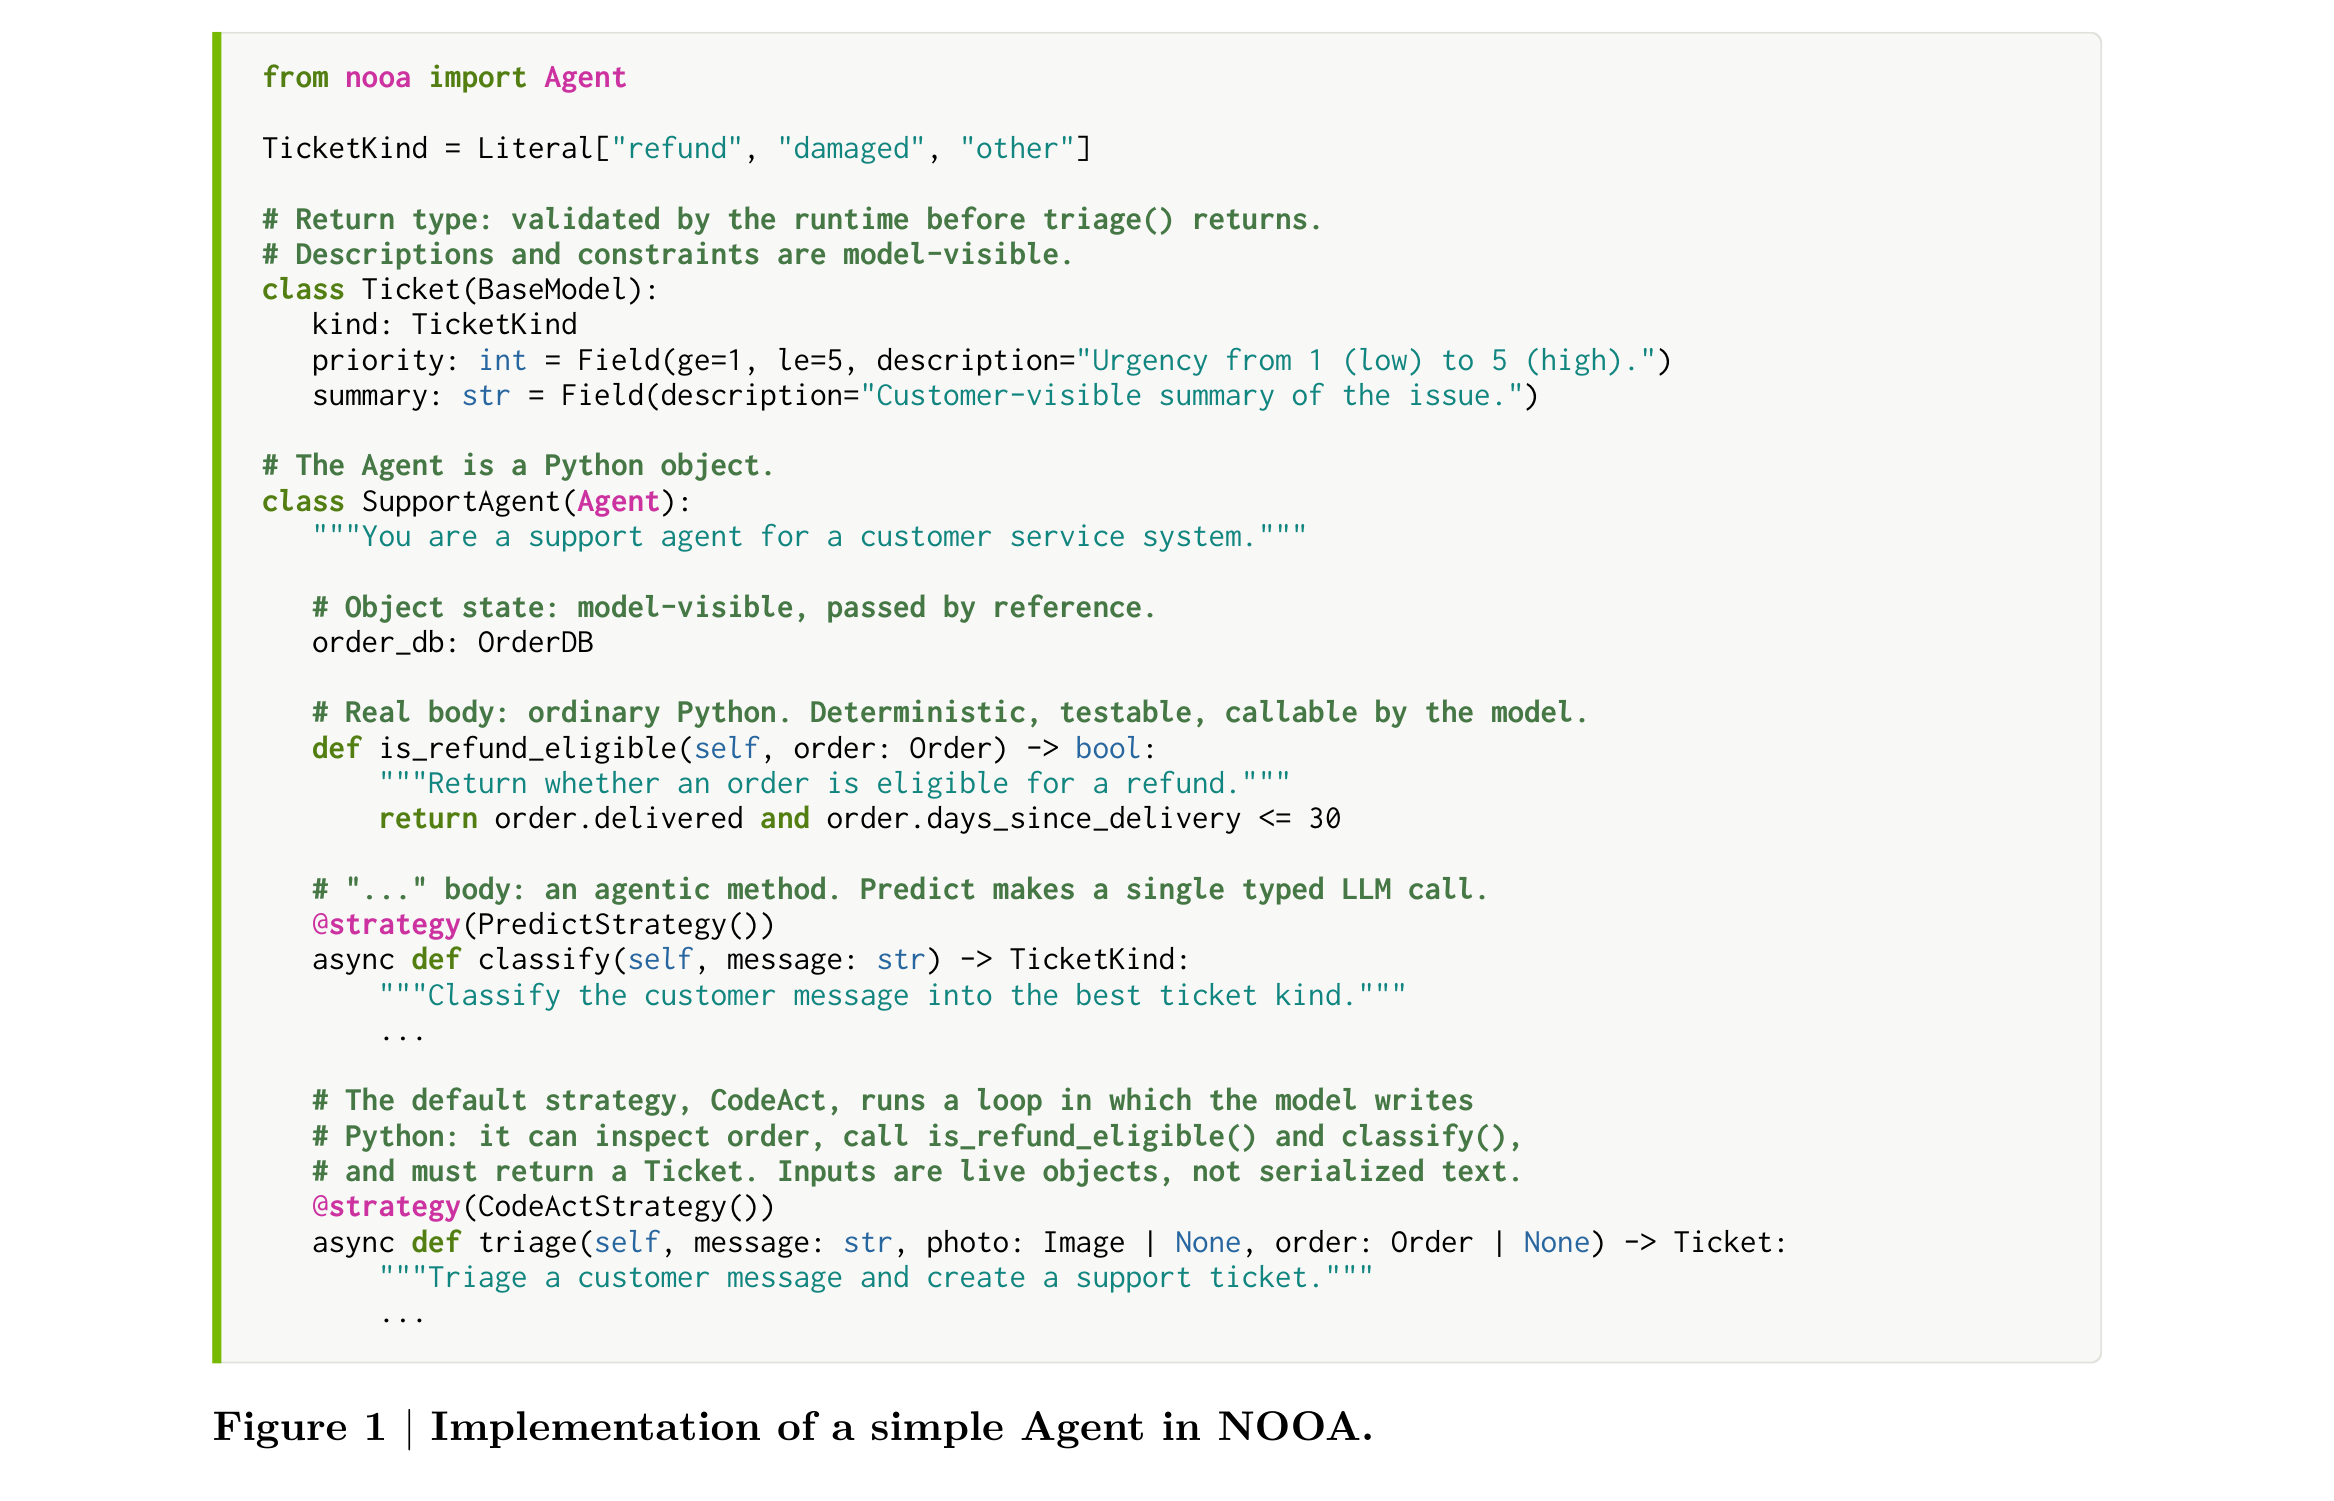
[Paper Review] NVIDIA-labs OO Agents: Native Python Object-Oriented Agents
An agent is not a bundle of prompt templates, tool schemas, and workflow graphs. It is a Python object: methods are actions, fields are state, docstrings are prompts, type annotations are contracts.
-
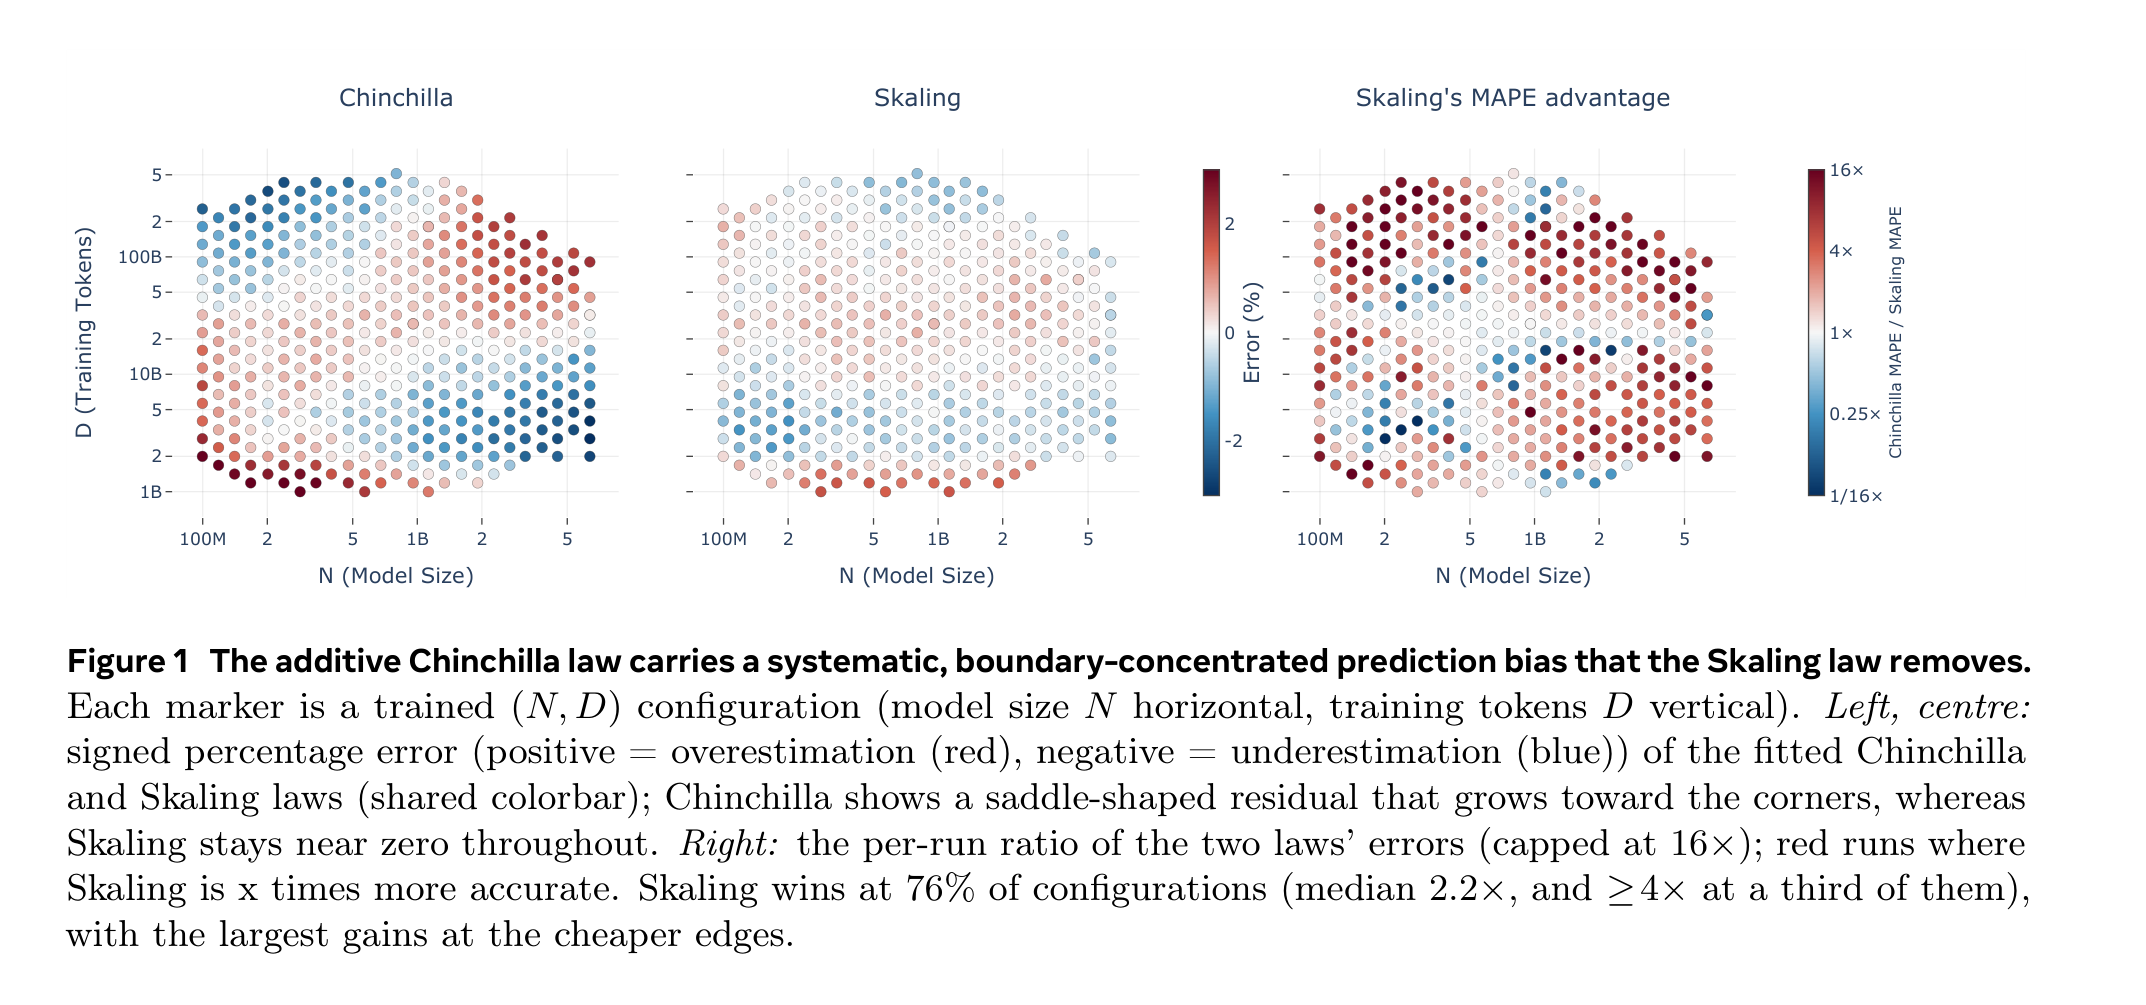
[Paper Review] Skaling: Chinchilla's Exponents Meet Kaplan's Coupling
Chinchilla's additive scaling law hard-codes the assumption that model size and data act independently. Measured mixed derivatives say otherwise, and one extra exponent cuts boundary extrapolation error by more than 10x.